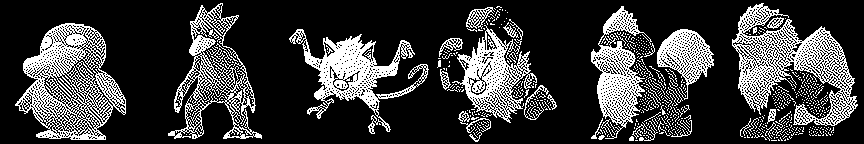Friday, April 10, 2015

MongoDB vs PostgreSQL for geo queries: postgres is indeed pretty much across-the-board faster

ok, I have some benchmark numbers. Two almost-identical databases, one in mongo, one in postgres, so I can actually compare apples to apples. In Mongo I have everything in one collection. In postgres, I have two tables: tweet_pgh, which is all the data, and tweet_pgh_small, which is just the data I need.

These tables are pretty optimized: the mongo collection has indices on user.screen name, coordinates (geospatial), coordinates.coordinates.0 and coordinates.coordinates.1. The sql tables have btree indices on user_screen_name and gist indices on the coordinates (clustered). Oh, and of course I've got PostGIS installed.

Every query here selects everything in a table, then iterates through it (just incrementing a counter) to simulate a semi-realistic use case.

Count in mongo: 3653683
Count in postgres: 3653278

Searching for single user stuff. User A has 2942 items, User B has 1928 items, User C has 3499 items. (using A, B, and C here for their anonymity instead of their real twitter handles.) First three are mongo, the rest are postgres.
Mongo: {'user.screen_name': '(user A)'} 11 sec
Mongo: {'user.screen_name': '(user B)'} 6 sec
Mongo: {'user.screen_name': '(user C)'} 24 sec
Postgres: SELECT * FROM tweet_pgh WHERE user_screen_name = '(user A)'; 5 sec
Postgres: SELECT * FROM tweet_pgh WHERE user_screen_name = '(user B)'; 6 sec
Postgres: SELECT * FROM tweet_pgh WHERE user_screen_name = '(user C)'; 6 sec
Postgres: SELECT * FROM tweet_pgh_small WHERE user_screen_name = '(user A)'; 1.9 sec
Postgres: SELECT * FROM tweet_pgh_small WHERE user_screen_name = '(user B)'; 1.4 sec
Postgres: SELECT * FROM tweet_pgh_small WHERE user_screen_name = '(user C)'; 1.9 sec

Huh. So for these it looks like postgres takes either the same amount of time, half the time, or 1/4 the time. But the real win comes from just having a smaller table.

Searching for geographic areas. And these are *with geospatial indices* on both tables. Here I'm searching for a 0.01-degree lat by 0.01-degree lng box, which has 69k things in it.

Mongo: {'coordinates': {'$geoWithin': {'$geometry': {'type': 'Polygon', 'coordinates': [[[-79.99, 40.44], [-79.99, 40.45], [-80, 40.45], [-80, 40.44], [-79.99, 40.44]]]}}}} - 53 min
Postgres: SELECT * FROM tweet_pgh WHERE ST_MakeEnvelope(-80, 40.44, -79.99, 40.45, 4326) ~ coordinates; 33 sec
Postgres: SELECT * FROM tweet_pgh_small WHERE ST_MakeEnvelope(-80, 40.44, -79.99, 40.45, 4326) ~ coordinates; 3 sec

Then try the same thing with a smaller box (0.001x0.001 degree) with way fewer things (~ 5):
Mongo: {'coordinates': {'$geoWithin': {'$geometry': {'type': 'Polygon', 'coordinates': [[[-79.899, 40.44], [-79.899, 40.441], [-79.9, 40.441], [-79.9, 40.44], [-79.899, 40.44]]]}}}}; 7 min
Postgres: SELECT * FROM tweet_pgh WHERE ST_MakeEnvelope(-79.9, 40.44, -79.899, 40.441, 4326) ~ coordinates; 0.16 sec
Postgres: SELECT * FROM tweet_pgh_small WHERE ST_MakeEnvelope(-79.9, 40.44, -79.899, 40.441, 4326) ~ coordinates; 0.07 sec
(still waiting on the mongo query for this)

Wow! So, wait. So the same query that took 53 minutes in Mongo took 33 seconds in postgres. And three seconds in a reduced-size table.

It's a little unfair; in Mongo you can do a little better by using $gt and $lt on the coordinates instead of doing a $geoWithin - it's easier to compare numbers than coordinates, if you're just doing a box query. So we have the following:

{'coordinates.coordinates.1': {'$gt': 40.45, '$lt': 40.46}, 'coordinates.coordinates.0': {'$gt': -79.95, '$lt': -79.94}} 20 min
{'coordinates.coordinates.1': {'$gt': 40.46, '$lt': 40.461}, 'coordinates.coordinates.0': {'$gt': -79.97, '$lt': -79.969}} 2 min

But this is still nowhere near the postgres time! So:

- use PostgreSQL with PostGIS for geo queries, not MongoDB
- this is especially true if you can index and cluster your dbs
- maybe postgres is a little better for simpler queries too
- in postgres (maybe in mongo too) there is a lot of benefit to be had from cutting down the size of your tables as small as possible

Saturday, January 24, 2015

Dealing with images on the Pebble watch

My goal: a Pokemon watch, that shows a pokemon each minute instead of the numerical minute. I figured I'd get 144x144 images, and then just display one each minute. The challenges:

1. You need black and white (not grayscale) images. This is easily solved with a tool like HyperDither, which uses "dithering" to create shades of gray using only black and white pixels.
For example, changes this color Bulbasaur into this black and white one:


This is nice. HyperDither has a batch mode, which works, but it actually makes slightly smaller PNGs if you do it one at a time.

2. Saving space. You get 24kb RAM per app and 96kb storage for images/fonts per app. It's not easy to fit all the images you need in 96kb. I wanted 60 images, so I had to average ~1.5kb per image. Luckily, black/white 144x144 PNGs are not so big. Using HyperDither, I got pretty close to 96kb, but not quite: I'd have 90kb of PNGs locally, but when I uploaded them to the Pebble, it converted them to "pbi" files, which are almost double the size.

(also note that if you include too many pictures that are over 96kb, you'll get a cryptic error: it'll compile fine, but then will say "Installation failed. Check your phone for details." but no real way to check your phone for details, and no hints about why it fails. You'll get a similar cryptic error if you upload an image but never reference it in your code (stack overflow related question).

Spriting
So I figured there was some overhead per-image, so I tried spriting, or combining multiple images into one big image, like so: (created with InstantSprite, which is awesome and free)


and then you just take a subset of that image at a time. Pebble provides a call, gbitmap_create_as_sub_bitmap, to do exactly that. However, a few problems:
- if you make an image that is too big (like 10 pokemon at a time, or 1440x144), then gbitmap_create_as_sub_bitmap just crashes the app with no feedback. I found that 6 pokemon (864x144) worked, while 1440x144 didn't. Not sure what the actual limit is.
- it doesn't even make the images smaller! 10 PNGs with 6 pokemon each is not really any smaller than 60 PNGs with 1 pokemon each.

uPNG. Forget Spriting.
So, forget spriting. I then found Matthew Hungerford's port of uPNG, which is a library that lets you use raw PNG files instead of converting them to PBI first. Just include the .c and .h files, use gbitmap_create_with_png_resource instead of gbitmap_create_with_resource, and then edit your appinfo.json file to change the type of each image from "png" to "raw".
(editing your appinfo.json may require pushing your code from CloudPebble to Github, then cloning it locally, editing the file, committing and pushing your change. also, you might have to move your image files from resources/images/foo.png to resources/data/foo.png. anyway, this is nice, because you can then upload a bunch of images by editing a text file instead of uploading through the GUI a lot.)

He also provides scripts to transform images to B/W or dithered first, which ended up saving a few kb in my case.

In the end, thanks to uPNG, I had 80kb of images that actually stayed 80kb. (plus a little bit of overhead per image, but didn't matter.) Success! Here's my watch code on Github.

Other Tips
- Use logging, like: APP_LOG(APP_LOG_LEVEL_DEBUG, "hello"); - this took me too long to discover.

Sunday, October 19, 2014

Starting MongoDB on OS X

When you install MongoDB on a Mac with Homebrew, it spits out this important info:

To have launchd start mongodb at login:
    ln -sfv /usr/local/opt/mongodb/*.plist ~/Library/LaunchAgents
Then to load mongodb now:
    launchctl load ~/Library/LaunchAgents/homebrew.mxcl.mongodb.plist
Or, if you don't want/need launchctl, you can just run:
    mongod --config /usr/local/etc/mongod.conf

This is important because the MongoDB docs tell you to run it by "sudo service mongodb start", which doesn't work on macs. Macs use "launchctl" instead of "service" (and they work differently). The things that they launch are defined by plist files in ~/Library/LaunchAgents.

There used to be a thing called "brew services", but now if you use that, it will tell you that it's unsupported and will be removed soon, so I guess don't use it.

Or if you just want to start it for a little while now, you could just start it with "mongod", but that doesn't work because you have to tell it where the config file is, which tells mongo where the database should be. Of course, you might not know where the config file or the database are. That's what the last line (mongod --config ...) is for.

Another tip: MongoDB logs are stored by default in:
/var/log/mongodb/mongodb.log

Sunday, February 23, 2014

Making maps in python, step 1: installing dependencies

I want to plot some things on a map. I got one guide from here, that uses Basemap.

Basemap:
brew install geos
brew install gdal
brew install gfortran

pip install matplotlib
pip install numpy
pip install pandas
pip install shapely
pip install basemap --allow-external basemap --allow-unverified basemap
pip install scipy
pip install pysal
pip install Fiona
pip install descartes

Okay, geez, I had written a ton more in this Blogger window, it looked like it was saving my draft, but then it... somehow didn't? Jesus, nothing on computers ever works. All right, I'll try to recreate it:

on Ubuntu, I wanted to pip install as much as possible (because of virtualenv) so I did stuff like this:
sudo apt-get build-dep numpy scipy matplotlib
pip install numpy scipy matplotlib
I think I just used pip for pandas, shapely, pysal, descartes. Fiona required something else, like apt-getting gdal or something?

Kartograph:
Ubuntu: http://kartograph.org/docs/kartograph.py/install-ubuntu.html
OSX: pip install -r https://raw.github.com/kartograph/kartograph.py/master/requirements.txt worked, I think because I already had installed gdal via brew.

Cartopy:
Ubuntu: https://github.com/SciTools/cartopy/issues/46
OSX: https://github.com/SciTools/cartopy/issues/48

Monday, February 3, 2014

Python sentence segmentation, kind of quick and mostly legit

Sentence segmentation (splitting a big block of text into sentences) is not trivial. You can't just split on periods, for example, because you'll get tripped up on every Dr. and Ms. and etc. and so on! However, it's mostly solved and in libraries, so here's a quick way to do it in python.

NLTK is a pretty general-purpose natural language processing toolkit. You could install the whole thing via instructions on their website. But that will also install a lot of other NLP tools. Also, a lot of these tools can be trained, which makes them more accurate if you have training data, but more difficult to get started if you don't have such training data. To get a pre-trained model:

- download Punkt from NLTK Data (direct link to Punkt)
- unzip it and copy english.pickle into the same directory as your python file. This is the trained model, which has been serialized out to a file. (obviously, this assumes you're segmenting English text; if not, grab one of the other .pickle files.)
- in your python code, unpickle it like so:
import pickle
segmenter_file = open('english.pickle', 'r')
sentence_segmenter = pickle.Unpickler(segmenter_file).load()
- then call:
sentences = sentence_segmenter.tokenize(text)
(where "text" is a string containing all your text).

Sunday, December 1, 2013

Sony Smartwatch 2 Programming

Some tips:
- the documentation seems to be, well, sparse. The most helpful thing I've found was code samples. They released five with the SDK (Sample{Control, Widget, AdvancedControl, Sensor, Notification}Extension) and two more here (EightPuzzleExtension and OSS_MusicExtension). Load them up into Eclipse as Android projects, they mostly work out of the box.
- well, mostly. For EightPuzzleExtension, I had to add <uses-permission android:name="android.permission.READ_EXTERNAL_STORAGE" /> to the Android Manifest.
- also useful was Xiang "Anthony" Chen's HelloWatch post. All the example apps have 4 classes, and Anthony explains them better than I can. Almost all of my code went in the Extension app.

Here's the app I've been working on: MorseWatch. Mostly just takes in touch events. Also, I made a HelloSmartwatch app that uses accelerometers.

Maybe more details later. In the meantime, better to get some info and helpful links out there as soon as possible.

Excursions in rooting my Nexus 4

Man, I never really wanted to dig into phone rooting, but I recently went to do a Portable Wi-fi Hotspot and found that T-Mobile now blocks all data when I tether through my phone. (which is insane. why does T-Mobile care whether I'm using my phone or computer? I'm not using a ton of data. but anyway.)

I found this post, which explains how to edit one sqlite database to allow tethering again.

Unfortunately, it's in /data/data/..., which is only editable (or even viewable) if you have root access. (this is I think the same as root on mac/linux, which is roughly the ability to "sudo".) For some reason, Android makes this difficult.

Luckily, xda-developers to the rescue.
Nexus 4 Rooting Guide.
Backing up your phone before you root it.

How'd it go? Pretty smoothly. Wiped my phone, but the two-part backup in the link above (both the "adb pull" and the "adb backup" part) meant I didn't lose much. Had to reconfigure a couple minor things, not bad. And now I can tether!

The major steps, in my mind, are:
- back up your stuff
- unlock the bootloader (this is when your phone gets wiped)
- flash (install) the custom recovery
- install the SU app or something? a little unclear on this step, but it involves installing SuperSU.
- restore your data

A couple of gotchas:
- as usual when reinstalling everything on your phone, if you use two-factor authentication (as you should), generating some backup codes beforehand makes everything easier.
- on the "clockwork mod" site, all you need is the one in the "download recovery" column.
- don't download/install over-the-air Android updates. It breaks your root. (which is not a huge deal, but it means you have to re-flash the recovery and re-install the SU app.)